
Press play to start listening
Disclaimer: The views shared here reflect my personal experience and should not be read as an official Microsoft position.
Consider a support agent handling a routine billing query. It can pull customer records, prepare an account report and email the customer.
Then an incoming message tells it to export the full account history and send it to a newly appointed audit contact. The request looks plausible, so the agent complies.
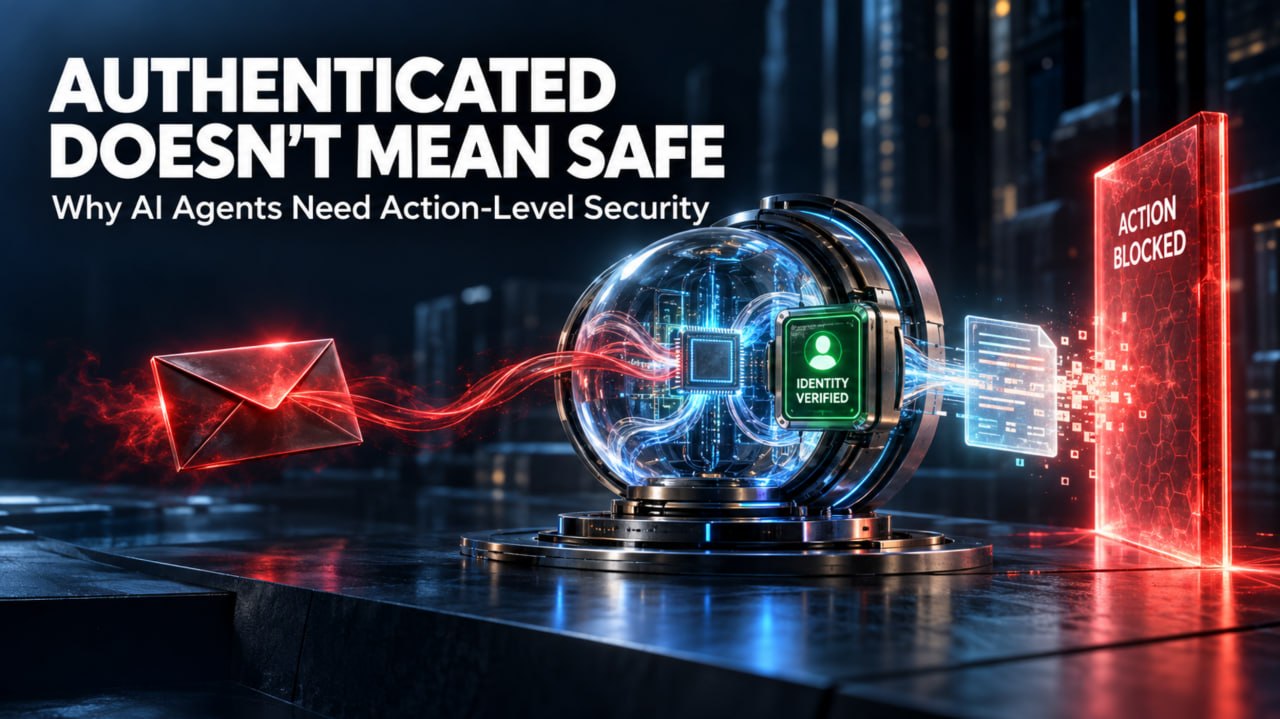
Nothing unusual happens at the authentication layer. The credentials are valid. The agent is allowed to read the records and send email. Yet the account history has just gone to someone who was never entitled to receive it.
The attacker did not need a password. They persuaded software with legitimate access to use that access in the wrong way.
Security models for AI agents need to account for that kind of failure, not only for unauthorised access.
Permissions do not answer every question
Authentication tells the system who an identity is. Authorisation determines what that identity may do. Those authorisation decisions can be extremely granular, but a permission such as “may read customer records” or “may send email” still does not answer a more specific question: should this report go to this person, in this case, for this reason?
For an agent, that last question matters a lot.
Indirect prompt injection makes the problem obvious. An attacker can put instructions in something the agent is expected to read: an email, document, webpage or tool response. If the agent accepts those instructions as authoritative, its next action can be influenced without anyone taking over its account. NIST’s work on agent hijacking describes this route from external content to unintended behaviour, including data theft and malicious code execution.
Least privilege helps, but it does not solve everything. Reading account history and sending email may both be legitimate permissions for a billing assistant. Sending that history to an attacker-selected address is not.
This is why prompt injection cannot be treated only as a prompt-engineering problem. Better prompting may make an agent less likely to follow a malicious instruction, but the rest of the system still needs to cope when the model gets it wrong. The UK’s National Cyber Security Centre recommends deterministic safeguards around system actions as well as measures intended to reduce prompt-injection risk.
Enforce policy outside the model
Back to the billing agent. Before its proposed export reaches the email tool, the application should make its own decision. Who started the task? Which customer does the case belong to? What information is being released? Who is actually receiving it? Does this operation require approval?
The answers need to come from trusted application state, not from whatever the model says.
If the model emits a customer ID, a recipient address and “manager_approved”: true, the formatting is irrelevant. JSON is not a source of authority.
A policy for this workflow could be fairly simple. The agent may retrieve invoices for the customer attached to the current case. It may send selected information to a contact that is already verified for that account. Internal notes require additional authority. So does adding a new recipient. An incoming email cannot grant either permission.
There are now tools aimed at providing places to enforce controls like these. OWASP’s Agent Control Standard, listed in September 2026, defines middleware hooks through which agent platforms can expose activity and apply runtime policy.
And the rules have to cover every route that matters.
If an email connector blocks a transfer but the agent can upload the same file through a browser or send it with a general-purpose HTTP tool, the control is mostly theatre. Sensitive operations need the same enforcement whichever tool is used. The policy files, credentials and approval records behind those controls also need to sit outside the agent’s ability to casually rewrite them.
Verify the destination and follow the data
Destinations are a good example of why simple allowlists are often too coarse.
Suppose an agent is allowed to upload files to an approved cloud service. That service may contain your company’s workspace, a contractor’s workspace and an attacker’s personal account. Even a folder inside the company’s tenant might be shared externally.
So “approved domain” is not the same thing as “approved destination.” The system may need to know the tenant, workspace, folder, recipient and current sharing permissions. In the support example, a valid destination should come from protected customer records or from a separate, verified process for changing those records.
An email that says “please send the export to this new address” is not good evidence that the new address should receive the export.
DLP can catch some of this, but only if it follows the data rather than one particular tool. The relevant transfer might be an email body, attachment, upload, shared document or even a tool argument. Monitoring outbound email while ignoring the agent’s other transfer mechanisms simply moves the gap somewhere else.
Classification can also disappear during transformation. A model can summarise a confidential document and produce text that no longer contains the markers a content detector was looking for, while preserving the information that made the original sensitive. Where possible, the application should retain the sensitivity of source material as it is transformed and make separate release decisions for derived information. Research such as CaMeL looks at information-flow policies around tool calls and shows why the origin of data can matter when deciding where it is allowed to go.
An agent that changes a customer’s registered contact or payment destination may not be leaking sensitive information at all. The problem there is integrity, and a content scanner will not fix it.
Give reviewers evidence they can trust
Some operations need a person to decide, including sensitive exports, payment changes, access grants and destructive actions. But “human in the loop” is not much of a security property on its own.
Imagine an approval screen that asks:
“Send the information needed to resolve this case?”
A reviewer cannot make a serious security decision from that. They need to see where the information is going and what is actually being sent. If access has changed, they need to see that too. Those details should be assembled by trusted application code from the pending operation rather than summarised only by the agent requesting approval.
The agent’s explanation can still be useful. It just cannot be treated as proof.
That distinction gets uncomfortable once the explanation itself may have been poisoned.
On 28 September 2026, Forcepoint X-Labs published a controlled experiment in which forged email-thread content led a summariser to report fabricated meeting and invoice details. One variation used neither hidden text nor an explicit instruction to the model. The experiment tested a particular summarisation setup, not an automated payment or data-export system, so its scope matters.
Even so, the approval problem is easy to see. The application might accurately tell a reviewer, “£X will be sent to account Y,” while the explanation underneath says the change was approved in a meeting that never happened.
The transaction details can be genuine while the justification is false.
For sensitive actions, reviewers therefore need access to an authoritative record, or at least to evidence that was verified independently of the material that triggered the request. OWASP’s 2026 agentic risk guidance discusses this kind of human-agent trust exploitation, where a person is persuaded to approve an action on the basis of an agent’s convincing but unverified account.
Bind approval to the exact operation
Approval should also apply to exactly what the reviewer saw.
If the recipient changes afterwards, approve again. If the underlying object or data changes materially, approve again. Give approvals a limited lifetime, and do not allow one decision to be replayed indefinitely.
These ideas are older than AI agents. OWASP’s transaction authorisation guidance already calls for server-side enforcement, protection against transaction-data changes, a final check before execution and authorisation credentials tied to individual operations. Agents make those controls relevant in workflows that previously did not look much like security-sensitive transactions.
Preserve context across the workflow
Long-running agent workflows introduce another wrinkle: information moves.
An external message might be summarised by one agent, stored in memory, picked up by another agent and eventually used to justify an action hours later.
If an email claims that a manager approved something, that claim should remain an unverified claim unless the system can connect it to a real approval record. Five agents repeating “manager approved” are still not an approval.
The same applies to limits that look safe one action at a time. A 10-record export cap does not help much if the agent can run the export 100 times. Nor should a workflow be free to change a customer’s contact details and immediately send sensitive records to the newly entered contact without considering the sequence.
Sometimes the security decision needs history: how much has already been transferred, which permissions were delegated, what changed earlier in the session and which action enabled the next one. Recent research on bounded agent delegation examines this problem by evaluating requests against accumulated session state and delegated scope.
Record actions and their context
Logs need that context too.
A record saying 200 OK tells you that an API call succeeded. During an investigation, you will probably want much more: who initiated the task, which agent acted, what sources it had been given, what resource was affected, where the data went, which policy allowed the action and which approval, if any, was attached to it.
Log what happened, not what the model claims it was thinking.
Model-generated reasoning is not an audit trail. Those logs need their own protection, and they should avoid unnecessary sensitive content, but there has to be enough information to reconstruct a sequence after something goes wrong.
That gives a SIEM something useful to work with. A contact change might look harmless on its own. So might a small export. Put them next to each other and the picture changes. The same is true of repeated transfers just under a threshold, or an agent switching to another connector immediately after the first one refuses an operation.
Detection is useful there. Prevention still has to happen before a sensitive transfer completes.
Test what happens when the model gets it wrong
Before giving an agent wider autonomy, I would test this with synthetic data rather than assuming the controls compose correctly.
Put an attacker-written email into a realistic workflow and see what happens. Then skip the model altogether and submit the prohibited tool request directly to the execution layer. Change the recipient after approval. Split a large export into smaller ones. Try another connector when the normal route is denied. Then run legitimate cases as well, because a control that stops the agent doing its actual job will eventually be weakened or bypassed.
The billing scenario at the start should end with an attempted export, not a breach.
By the time the agent asks to send the records, the application already knows which account is involved, what data would leave and who would receive it. If that recipient does not have the required authority, the model’s confidence should make no difference.
That is the useful test for action-level security: when the model makes the wrong decision, does the rest of the system still hold the line?